This article explains why Omnichannel Attribution can fail in Canadian Markets even when the underlying analytical model appears technically strong. It estimates how online and offline touchpoints contribute to conversion, while identity gaps, walled-garden platforms and the difference between observed credit and causal incrementality complicate interpretation. The main failure modes arise earlier in the system: fragmented identifiers and definitions, weak ownership, vague objectives, poor baselines, proxy metrics that become the goal, and workflows that do not convert analytical signals into timely action. Automation can also increase friction through duplicate systems, excessive alerts, unclear decision rights and recommendations that arrive too late to matter. The article stresses that incentives deserve the same scrutiny as algorithms because vendors, departments, managers and analytical teams may all optimize for visible or self-serving measures. Implementation discipline, reliable data and usable operating processes are presented as more important than adding another layer of model complexity.
By July 14, 2026, omnichannel attribution was not only a specialist analytics conversation, but also one for management in Canada. The question was no longer just if the scores, forecasts, rankings or recommendations of the advanced models will be produced. There was a growing concern about whether these outputs continued to be reliable, understandable, fair and economically useful when made into decisions. As organizations invest in omnichannel attribution, it became more important than just performing a technical job, it became a job of evidence-based decision quality. Omnichannel attribution is an attempt to quantify the impact of many touch points, both online and offline, that lead to conversion or another business goal.
Canadian markets introduce additional practical challenges due to varying retail environments, platform dependency, different communication contexts (both bilingual and English), privacy expectations, and the unevenness of integration between digital and physical channels. When identity resolution is incomplete, or journeys can only be seen within the walls of the walled garden, attribution models can become fragile. The benefit of incrementality testing is that observed credit does not necessarily equal causal contribution, and that there is a significant safety to this component. Failure to implement seldom starts with a dramatic model failure. Typically, value dissipates because of weak joins in data, poor ownership, fuzzy goals, nonstandard processes, and decision-supportive dashboards that don't connect to the decisions.
A correctly designed system may therefore be unable to work when all of its parts look like they're working. Failure analysis should be done from the data collection to the organizational response. One of the frequent causes is data fragmentation. The same underlying activity may be given different identifiers, taxonomies, definitions and timestamps by different channels, teams, vendors or workplace systems. Errors in integration are then camouflaged as behavioural insights. Basic controls that have disproportionate impact are data lineage, reconciliation tests, missingness analysis, and shared definitions. A second failure mode is when a proxy metric becomes the goal. Once optimization begins, conversions or likelihood of conversions, engagement, attribution credit, sentiment, or click activity may lose their link to long-term business value.
Then, teams do better as the measured proxy gets better, and trust with customers or employee satisfaction or outcomes become worse. Balanced scorecards decrease that risk by adding together indicators of short-term and long-term. When automation doesn't come with workflow reengineering, it can stall organizational adoption. Staff receive additional warnings, multiple systems, confusion over who is responsible and limited rationale for what to do. With low adoption rates, it is then attributed to resistance despite the fact that the operating model design provided logical grounds for avoidance. Successful implementation eliminates duplicative steps and makes decision rights more clear. Incentives should be looked at as carefully as algorithms for failure reviews.
Renewal people can maximise for renewal, departments can stake budgets, managers can prioritise activity that is more likely to be seen, and analysts can guard their models from those developed by trusted teams. When they are independent, and have clearly stated success criteria, they are less linked to those incentives. Post implementation reviews should be carried out comparing the promised value with the measured value on the basis of the original baseline. Analytical governance in Canada included private sector privacy requirements, together with growing public sector requirements for automated decisions. Structured assessment has become a key point of reference for responsible automation because of the federal Directive on Automated Decision-Making that mandated impact assessment and risk-calibrated safeguards for covered administrative systems.
The Office of the Privacy Commissioner of Canada reiterated that software is not the basis for an organization's responsibility for a decision, just because it is part of a computer-based decision-making process. Explicit uncertainty communication is also essential for good analytical practice. Point estimates can give the illusion of precision when there is low coverage or when conditions are rapidly changing. Operational teams can see uncertainty through prediction intervals, sensitivity ranges, scenario analysis and confidence categories. Use of uncertainty language will help participants make proportional responses to the questions rather than accepting all scores. Vendor governance is also important to consider because the external platform might change models, interfaces, data processing or even terms in an unimbalanced way with the internal release cycles.
The following issues should be covered in contracts: documentation, change notification, audit access, incident response, security, data retention and exit arrangements. Independent validation is still required with internal teams due to vendor assurance being not sufficient to replace the need for organization specific evidence. The value of a business needs to be assessed in the context of a full business lifecycle. Development costs are not the only costs; integration, training, monitoring, data maintenance, review time, remediation and retirement are other costs. The costs that reoccur should be compared against the benefits. A model that requires ongoing manual maintenance, can be presented well in a pilot, but yields poor net value on scaling.
When the results of organizational learning are fed back to the design of the processes, the learning process becomes a critical source of return. Constant failures of data to match judgment can reveal the absence of variables or the need for updated rules. Surprisingly, multiple mistakes in the model can expose problems in labels or business definitions. If those signals are viewed as learning opportunities, rather than retraining on a scheduled basis, it is a better decision system. To the extent that they impact on omnichannel attribution, business unit, customer group, geography, channel and operating regime should also be segmented. Shared metric definitions and data dictionaries help minimize disagreements, which can only be resolved once performance starts to suffer.
The key is that, when you do a baseline comparison, you might not see any apparent improvement in omnichannel attribution, even though it appears to have occurred. Independent review is most effective when reviewers can recreate important results from input, assumptions (with documentation), and version-controlled model artifacts or code. Operational teams don't have to deal with numerous indicators on a large dashboard that have no clear escalation logic. Rare inputs, missing inputs, sudden volume shifts or unusual cases can cause brittle behaviour, which can be detected with scenario testing before deployment. Disputes that can only be resolved once performance starts to suffer are prevented thanks to the data dictionary and common metric definitions.
Average performance and tail outcomes should be monitored as both will be of greater concern when errors are large. Independent review is most effective when reviewers can recreate important results from input, assumptions (with documentation), and version-controlled model artifacts or code. Change management also requires users at the front-end as any reduction in the value realized due to workflow friction will do so despite the analytical performance remaining unchanged. By pushing systems into situations where they have to deal with uncommon scenarios, missing inputs, sudden volume increases or unfamiliar cases, scenario testing can help to uncover brittle behavior before deployment. A clear retirement rule is important because it allows for the elimination of outmoded models even after there is evidence for replacement.
Monitoring should be done both for average performance (as well as for tail outcomes) since large deviations are more important than small deviations in the mean. Decision logs serve as a great piece of evidence for future review and provide connections between recommendations, overrides, context, and outcomes. Change management also requires users at the front-end as any reduction in the value realized due to workflow friction will do so despite the analytical performance remaining unchanged. Evaluates the consequences of a false-positive, false-negative, delayed action, and unnecessary escalation; this results in a more realistic cost-sensitive evaluation. A clear retirement rule is important because outdated models continue to exist because of organizational inertia after there is evidence that they should be retired.
Periodic challenge exercises can be carried out to determine if an easier rule, a revised baseline or alternative model will lead to better performance than the existing model. Decision logs are useful for future use when reviewing, tying together recommendations, overrides, context, and actual outcomes. To the extent that they impact on omnichannel attribution, business unit, customer group, geography, channel and operating regime should also be segmented. Whereas the basic definition of cost sensitive evaluation is to assign varying consequences to false positives, false negatives, delayed action, and unnecessary escalation, it improves realism. This is why having baseline comparisons is important as these can be the difference between a perceived improvement in omnichannel attribution and vanishing if you consider seasonal trends, policy changes, or previous trends.
Periodic challenge exercises can be used to determine if there is a simpler rule, updated baseline, or different model that is more effective than the current rule. Operational teams don't have to deal with a huge dashboard with no obvious escalation structure, instead they have a handful of indicators that decide whether to go to the next step. The problem with omnichannel attribution in Canada is typically more widespread than just a technical one. The quality of the outcomes depends on the quality of data, realistic goals, incentives that align, workflows that are usable, and evidence of the alignment of modeled signals with actual value. The discipline of implementing (and following) can save more projects than another level of algorithmic sophistication.
CITE THIS ARTICLE
CHOWDHURY, S. A. (2026). When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets. https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2
S. A. CHOWDHURY, “When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets,” 2026. [Online]. Available: https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2
CHOWDHURY, S. A. (2026) ‘When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets’. Available at: https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2
CHOWDHURY, SABBIR AHMED. “When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets.” 2026, https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2.
SABBIR AHMED CHOWDHURY. “When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets.” (2026). https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2.
CHOWDHURY SA. When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets. 2026. https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2
@misc{article_b47c064192505084be442f73094d82a2,
  title = {When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets},
  author = {SABBIR AHMED CHOWDHURY},
  year = {2026},
  url = {https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2},
}
TY  - GEN
AU  - SABBIR AHMED CHOWDHURY
TI  - When Omnichannel Attribution Fails: Implementation Lessons from Canadian Markets
PY  - 2026-07-14
UR  - https://www.sabbirresearchhub.com/article/b47c0641-9250-5084-be44-2f73094d82a2
ER  -
AI-enabled employee engagement includes survey analytics, sentiment analysis, personalized recommendations, workforce listening, communication tools, and manager decision support, all operating within sensitive employment relationships. The article compares humans and algorithms on matched tasks, information, and outcome horizons rather than benchmark scores alone. Human context and judgment are weighed against algorithmic scale and repeatability, while hybrid rules, disagreement analysis, blind
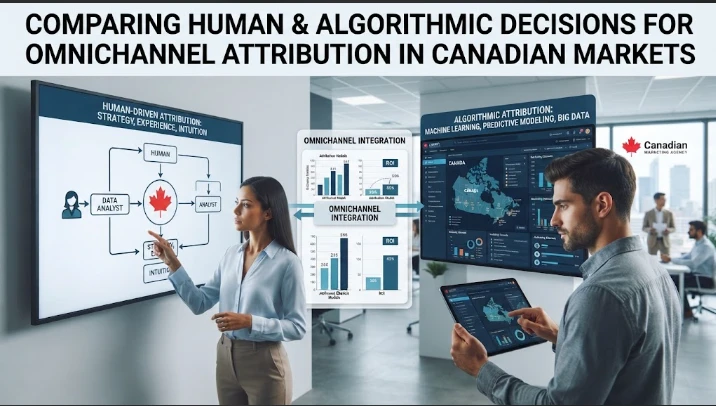
This article compares human and algorithmic decision making for Omnichannel Attribution in Canadian Markets, focusing on downstream decision quality rather than prediction accuracy alone. It estimates how online and offline touchpoints contribute to conversion, while identity gaps, walled-garden platforms and the difference between observed credit and causal incrementality complicate interpretation. Human judgment contributes context, tacit knowledge, strategic interpretation and sensitivity to
AI business model renewal concerns changes in value creation, value delivery, and value capture through AI-enabled services, workflow redesign, personalization, pricing support, and new information products. The article emphasizes real-world causal testing through random assignment, phased rollouts, encouragement designs, or cluster experiments. It calls for pre-specified outcomes, contamination controls, comparisons among human-only, algorithm-only, and hybrid workflows, and stop rules when har