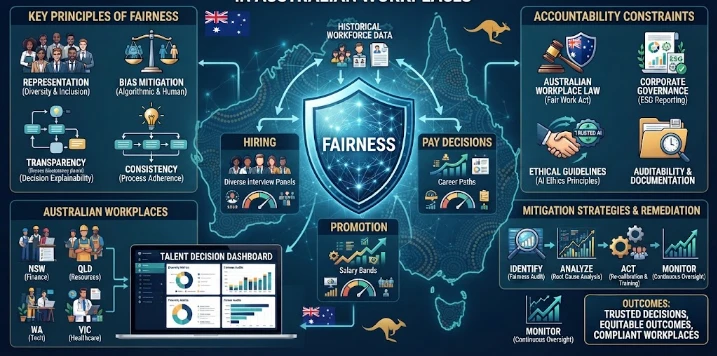
Talent decision fairness covers recruitment, promotion, performance management, development, scheduling, and related employment decisions, with particular attention to proxies, subgroup outcomes, accessibility, and calibration. The article keeps accountability with the deploying organization through named owners, separation of development and approval authority, reproducible documentation, meaningful human oversight, and formal reassessment when scope, data, vendors, or policies change. Override patterns and retirement rules are treated as governance evidence rather than administrative details. The Australian discussion connects AI use with Privacy Act obligations, anti-discrimination responsibilities, human oversight, and concerns about unfair outcomes from biased data, proxies, or design choices. Across the analysis, business value is tied to baselines, uncertainty, subgroup effects, workflow fit, lifecycle cost, vendor accountability, scenario testing, and decision records. The overall message is that analytical performance becomes credible only when it improves real decisions under clearly defined operating and governance conditions. Independent review, common metric definitions, and periodic challenge exercises are also presented as safeguards against hidden deterioration, stale assumptions, and continued use of systems that no longer justify their cost or risk.
In Australia, by 16 June 2026, the conversation around talent decision fairness had shifted from the specialist analytics arena to a wider management conversation. The question was no longer if advanced models could create scores, forecasts, rankings, or recommendations. This focus shifted to whether those outputs continued to be reliable, understandable, fair and economically useful when used in real decisions. In the case of organizations that invest in talent decision fairness, the shift brought in a new concept of successful implementation; not just technical performance, but proof-based decision quality. Talent decision fairness extends to recruitment, promotion, performance management and development, scheduling and other employment decisions. Thus, fairness cannot be captured in a single hiring measure since it is experienced at various stages.
Australian employers also should be mindful of the possibility that model features might be proxies for protected characteristics or socioeconomic status. Risks not captured by aggregation accuracy can be identified using group metrics, calibration checks, accessibility review, and qualitative assessment. The first principle of accountability is that the organization that deploys an analytical system retains its responsibilities. Legal, managerial, and ethical accountability is NOT delegated by the transfer of the tasks of scoring, ranking, forecasting, or recommendation to software. Governance, therefore, requires named owners for data, model behaviour, business rules, approval, monitoring, incident response and retirement. Fuzzy ownership leads to holes just when the surprises call for quick response. Development authority and approval authority are clearly distinct through a strong governance framework.
Model builders can provide an explanation of data, objectives, assumptions, and limitations; independent reviewers can review validation, fairness, security, compliance, and business consequences. The decision makers at the senior level then decide whether there is still risk within the tolerance of the organization. Separation decreases the likelihood that the technical buzz will be the only reason the software is deployed. A backbone of accountability thus becomes documentation. It is useful to record data provenance, definition of features, construction of the target, versions of the model, testing of the model, who will use it, who will not, thresholds, overrides, known limitations, and monitoring plans. Changes in material following deployment should also be documented.
Only then could a later investigation rely on memory and the individual technical artifacts. Human review is a more specific requirement than generic review. A reviewer should have a sufficient amount of information, authority, time and competence to challenge an automated recommendation. Patterns that are overridden should not be ignored—the presence of too many overrides might indicate a lack of calibration, context, or adoption. On the other hand, if the overrides are very close to zero, the model might not be as good as it could be and it could be an example of automation bias. Constraints for accountability can also help design in that they can require clarity of purpose.
This sort of "good ol' boy" network should not simply be allowed to become a gatekeeping system without a re-evaluation. An intervention that works in one population should not be replicated in another context until it is proven to be effective. Formal reassessment is best when scope changes, retraining events, vendor updates and policy changes occur. National discussion on increased protections for high impact AI continued as Australian organizations were still subject to anti-discrimination laws and privacy laws. In 2024, the OPIC provides guidance on the Privacy Act in relation to the use of personal information in AI products and emphasises privacy governance. The Australian Human Rights Commission also pointed out the potential for discrimination in algorithmic decision-making processes and released guidance for employers to ensure compliance when recruiting.
Clear uncertainty communication is also a key component of good analytical practice. A point estimate can give the false impression of accuracy, particularly if data is sparse or situations are dynamic. Uncertainty is made visible to the operational teams through prediction intervals, sensitivity ranges, scenario analysis, and confidence categories. Remove uncertainty language to enable proportional responses instead of automatic responses to all scores. Vendor governance must be taken into account, as a vendor may change models, interfaces, data processing, or terms without keeping up with internal release cycles. Documentation, change notification, audit access, incident handling, security, data retention, and exit arrangements are all issues that should be covered in contracts.
Even though vendor assurance can't replace organization-specific evidence, it's important to have independent validation within the internal team. Assess the business value across the business lifecycle. The integration, training, monitoring, data maintenance, review time, remediation and retirement require resources, too. Comparing benefits with those recurring costs. A model necessary to be continually adjusted by hand could be a show-stopper in a pilot but the net performance would be weak after scale. Where results are fed back into process design, the learning within the organization is a significant source of return. If there is continued disagreement between data and frontline judgment, missing variables or rules that need to be updated can be found.
If errors are repeated, there may be a problem with the labels or definitions in business. That's a better decision system than just retraining on the schedule because those signals are treated as learning opportunities. Chunks of evidence should also be broken down by business unit, customer definition, geographic, channel, or operating regime, when those segments have an impact on the fairness of the talent decision. Data dictionaries and common metric definitions eliminate conflicts that may only appear when performance goes astray. Comparisons are critical because there can be some apparent improvement in talent decision fairness that appears to be lost once seasonal patterns, policy changes, or prior trends are accounted for.
Independent review is most effective when the reviewers have the ability to re-create some of the important findings from raw data, assumptions, and model or code artifacts that have been documented and version controlled. Instead of having a big dashboard with no escalation logic, operational teams get a few relevant indicators to help with decision making. By pushing systems into rare conditions, missing inputs, volume changes, or strange cases, scenario testing can reveal brittle behavior prior to deployment. Data dictionaries and common metric definitions can eliminate disagreements that can only be resolved once performances start to wane. Average performance and tail outcomes should both be monitored as severe errors can have more impact than modest shifts in a mean statistic.
Independent review is best performed by reviewers who can replicate important findings from raw inputs, assumptions documented in a version-controlled document, and the model and/or code elements. Feedback from the frontline users is also important to change management because of the impact of workflow friction on the value delivered, even if the analytical performance is stable. By pushing rare inputs, unexpected cases, unexpected volume changes or sudden transitions, scenario testing can reveal brittle behavior before deployment. The importance of a clear retirement rule is that if a model is no longer effective, it can remain in an organization for a long time due to the resistance of the people. There should also be monitoring for average performance as well as tail outcomes as the extreme errors may be more important than the modest movement in a mean.
A decision log provides useful evidence for subsequent review which connects recommendations, overrides, contextual considerations and results. Change management also should be informed by the feedback from the front line users, as some workflow friction may cause loss of value even if analytical performance remains constant. Cost-sensitive evaluation enhances realism by varying consequence functions for false and true positive responses, delayed action, and unnecessary escalation. Clear retirement rule is important because legacy models may remain in place due to organizational inertia even though there is evidence to recommend that they should be replaced. Challenge exercises every few years can help determine if a more elementary rule, newer baseline, or alternative model works better than the existing rule.
Decision logs provide useful documentation for future review, connecting recommended decisions, overrides, context and actual results. If there are business units, segments, customers, geographies, channels or operating regimes that impact the fairness of talent decisions, those should be segmented as well. Cost sensitivity creates realism, as it will allow for different consequences for false positives, false negatives, delayed action, and unnecessary escalation. Comparisons to a baseline are necessary because apparent improvement in the fairness of talent decisions can be lost when seasonal influences, changes in policy, and previous trends are considered. Governance is credible and means accountability is visible in the day-to-day running of the organisation for talent decision fairness in Australia.
Named ownership, independent validation, precise control by humans, documented scope and lifecycle monitoring make defensible control. This statement does not mean to say that there is no uncertainty, but rather that there is uncertainty that can be controlled, and that there is always responsibility behind the decisions of the organization.
CITE THIS ARTICLE
CHOWDHURY, S. A. (2026). Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces. https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7
S. A. CHOWDHURY, “Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces,” 2026. [Online]. Available: https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7
CHOWDHURY, S. A. (2026) ‘Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces’. Available at: https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7
CHOWDHURY, SABBIR AHMED. “Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces.” 2026, https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7.
SABBIR AHMED CHOWDHURY. “Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces.” (2026). https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7.
CHOWDHURY SA. Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces. 2026. https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7
@misc{article_4db9d2618a995450bf81b0fc323f26f7,
  title = {Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces},
  author = {SABBIR AHMED CHOWDHURY},
  year = {2026},
  url = {https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7},
}
TY  - GEN
AU  - SABBIR AHMED CHOWDHURY
TI  - Governing Talent Decision Fairness Under Accountability Constraints in Australian Workplaces
PY  - 2026-06-16
UR  - https://www.sabbirresearchhub.com/article/4db9d261-8a99-5450-bf81-b0fc323f26f7
ER  -
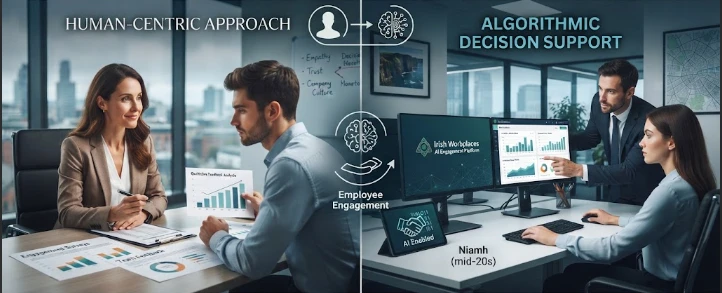
AI-enabled employee engagement includes survey analytics, sentiment analysis, personalized recommendations, workforce listening, communication tools, and manager decision support, all operating within sensitive employment relationships. The article compares humans and algorithms on matched tasks, information, and outcome horizons rather than benchmark scores alone. Human context and judgment are weighed against algorithmic scale and repeatability, while hybrid rules, disagreement analysis, blind
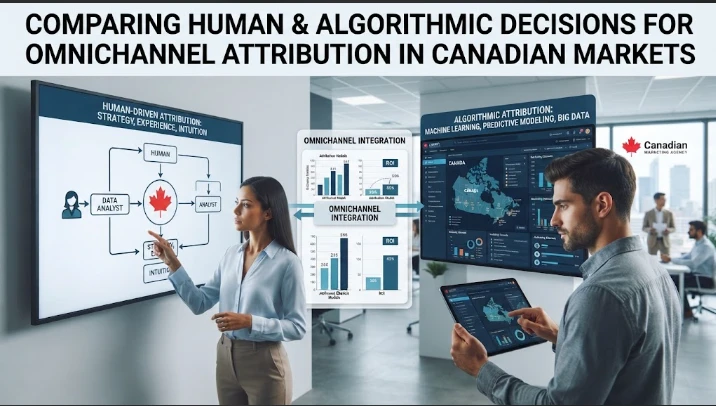
This article compares human and algorithmic decision making for Omnichannel Attribution in Canadian Markets, focusing on downstream decision quality rather than prediction accuracy alone. It estimates how online and offline touchpoints contribute to conversion, while identity gaps, walled-garden platforms and the difference between observed credit and causal incrementality complicate interpretation. Human judgment contributes context, tacit knowledge, strategic interpretation and sensitivity to
AI business model renewal concerns changes in value creation, value delivery, and value capture through AI-enabled services, workflow redesign, personalization, pricing support, and new information products. The article emphasizes real-world causal testing through random assignment, phased rollouts, encouragement designs, or cluster experiments. It calls for pre-specified outcomes, contamination controls, comparisons among human-only, algorithm-only, and hybrid workflows, and stop rules when har