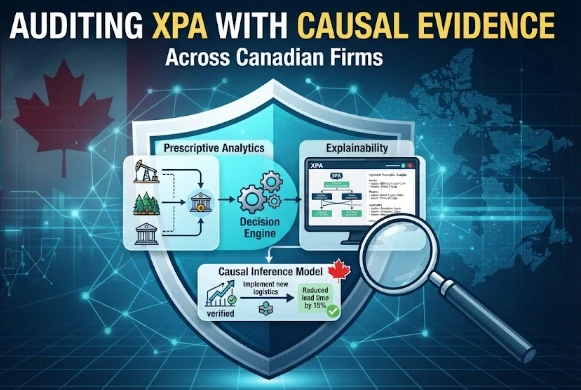
Explainable prescriptive analytics goes beyond predicting outcomes by recommending actions under objectives and constraints, which requires separating predictive models, causal assumptions, optimization rules, and business limits. The article shifts attention from prediction to intervention by defining treatment, outcome, population, time horizon, and the counterfactual. It highlights confounding in historical business data and uses experiments, natural experiments, quasi-experimental designs, subgroup analysis, and operational economics to test whether recommended actions actually cause better outcomes. The Canadian discussion combines privacy obligations with public-sector automated-decision rules, emphasizing impact assessment, transparency, accountability, fairness, and lifecycle attention to personal information. Across the analysis, business value is tied to baselines, uncertainty, subgroup effects, workflow fit, lifecycle cost, vendor accountability, scenario testing, and decision records. The overall message is that analytical performance becomes credible only when it improves real decisions under clearly defined operating and governance conditions. Independent review, common metric definitions, and periodic challenge exercises are also presented as safeguards against hidden deterioration, stale assumptions, and continued use of systems that no longer justify their cost or risk.
As of 30 June 2026, in Canada, prescriptive analytics was shifting from a specialist niche discussion to a general management discussion, specifically explainable prescriptive analytics. The question that was no longer in question was whether advanced models could make scores, forecasts, rankings, or recommendations. The question of whether such outputs were reliable, understandable, fair and/or economically useful when linked to real decision-making became a growing focus. That transition made the difference for organizations taking a plunge into explainable prescriptive analytics: It brought the element of evidence-based decision quality into the picture and moved the bar from just technical performance. Prescriptive analytics is more than just prediction; it is a recommendation of actions that are taken under objectives and constraints.
Explainability is particularly relevant as managers should also know the reasons for preferring one intervention over another, the nature of the assumption(s) underlying the recommendation, and how sensitive the outcome is to changes in the input(s). To enhance prescriptive systems, it is important to disentangle predictive systems, causal assumptions, optimization rules and business constraints within Canadian firms. This separation simplifies auditing as the audit of each layer can be conducted independently. Auditing using causal evidence shifts the focus from prediction of outcomes from an analytical system to whether recommended actions lead to improved outcomes. Evidence of interventions is needed to make prescriptive decisions, and patterns can be identified through correlation.
A variety of approaches to that evidence exist: randomized experiments, natural experiments, quasi-experimental designs and well-specified causal models. The first step in a causal audit is to establish the definition of treatment, outcome, population, and time horizon, all while accounting for assumptions. It is impossible to have a clear conclusion if interventions are ambiguous. To propose a change in price, reallocation of resources, change in content, or reordering of a market, there must be a clear counterfactual: "What would have happened if this had not been done?". Then the audit should see if it is possible to get the missing counterfactual from available data in a credible way. Confounding should be noted as it is a special case as business data records decisions made in the past instead of neutral observations.
High value customers may have more attention given to them, good markets may be able to allocate more resources and attractive staff may be offered better opportunities. Those prior choices could be confused for causal effects by naive models. Prescriptive claims are only credible if there is design-based evidence or an explicit adjustment strategy. Explanations serve as a means of reinforcing a causal audit by revealing treatment rules, effect heterogeneity, and assumptions. By itself it can't prove association equals causation. Auditors should consider if explanations are consistent across samples, if there are any differences in the treatment effects across groups, and if recommendations extend beyond the support they have. Beware of large effects in poorly supported areas.
The final conclusions of the audit should link statistical evidence with the value of the operations. Average treatment effects may obscure the existence of segments of negative outcomes, and statistically significant gains may be insufficient for the implementation costs. There are three key factors to take into account when setting decision thresholds: uncertainty, capacity, fairness, compliance, and opportunity cost. A causal audit is successful only when it affects decisions about deployment, not just when it results in another model score. Canadian data analytics governance has incorporated the private sector privacy requirements with the more explicit public sector regulations for decisions made by automated systems. Structured assessment was becoming a facet of responsible automation as the federal Directive on Automated Decision-Making mandated impact assessment and risk-calibrated safeguards for covered administrative systems.
The Office of the Privacy Commissioner of Canada reiterated that software is not the basis for an organization's responsibility for a decision, just because it is part of a computer-based decision-making process. Explicit uncertainty is also crucial to good analysis. Point estimates can lead to false precision, particularly where data cover is low or change rapidly. Uncertainty is made visible for operational teams via prediction intervals, sensitivity ranges, scenario analysis and confidence categories. Use of uncertainty language will help participants make proportional responses to the questions rather than accepting all scores. It is also equally important to consider vendor governance as external platforms can modify their models, interface, data processing or terms and conditions, which may not match the internal release cycles.
The following issues should be covered in contracts: documentation, change notification, audit access, incident response, security, data retention and exit arrangements. Independent validation is still required with internal teams due to vendor assurance being not sufficient to replace the need for organization specific evidence. The value of a business needs to be assessed in the context of a full business lifecycle. Development is just the start—the integration, training, monitoring, data maintenance, review time, remediation and retirement take their toll. The costs that reoccur should be compared against the benefits. A model which requires constant manual remodelling can seem impressive in a pilot stage but result in poor net value once scaled up.
When the results of organizational learning are fed back to the design of the processes, the learning process becomes a critical source of return. Constant failures of data to match judgment can reveal the absence of variables or the need for updated rules. The presence of repeated model errors can indicate problems with the labels or business definitions. It is a more powerful decision system than just retraining regularly because those signals are used as learning opportunities. Giving each piece of evidence a business unit, a customer group, a geography, a channel, or an operating regime that impacts explainable prescriptive analytics would also be beneficial. Data dictionaries and shared metric definitions can minimize disagreement that can only arise when performance starts to fall.
Baseline comparisons are critical, as what appears to be a pattern of improved performance in explainable prescriptive analytics may be put in jeopardy by introducing seasonal trends, policy changes, and/or prior trends. Independent review is most useful when reviewers can replicate some of the key results from the raw data, assumptions and artifacts of the model/software that was version controlled. The operational teams are not overwhelmed with a large dashboard of indicators, but rather a small number for making decisions with a clear escalation logic. Rare combinations, missing inputs, sudden volume changes, or unexpected cases can result in brittle behavior prior to deployment, depending on the scenario tests performed. Shared metric definitions and data dictionaries help minimize disagreements, which can only be resolved once performance starts to suffer.
Average performance and tail outcomes should be monitored as both will be of greater concern when errors are large. Independent review is most effective when reviewers can recreate important results from input, assumptions (with documentation), and version-controlled model artifacts or code. Change management also requires users at the front-end as any reduction in the value realized due to workflow friction will do so despite the analytical performance remaining unchanged. By simulating rare inputs, missing inputs, sudden volume changes or unexpected situations, scenario testing can reveal brittle behavior prior to deployment. An obvious rule to retire is important because of organization inertia, which can keep an outdated model alive when it's time to end it.
Average performance and tail outcomes should be monitored as both will be of greater concern when errors are large. Decision logs are useful for future use when reviewing, tying together recommendations, overrides, context, and actual outcomes. Change management also requires users at the front-end as any reduction in the value realized due to workflow friction will do so despite the analytical performance remaining unchanged. Whereas the basic definition of cost sensitive evaluation is to assign varying consequences to false positives, false negatives, delayed action, and unnecessary escalation, it improves realism. A clear retirement policy is important because the beliefs of the employees can stick around in the organization long after the proof of the need to retire comes in.
A periodic challenge exercise can be used to determine if a simpler rule or revised baseline or other model can do the job better than the current system. Decision logs provide great evidence for future consideration and connect recommendations, overrides, context and actual results. Another method of segmenting evidence would be by business unit, customer group, geographic, channel, or operating regime if those factors impact explainable prescriptive analytics. Whereas the basic definition of cost sensitive evaluation is to assign varying consequences to false positives, false negatives, delayed action, and unnecessary escalation, it improves realism. Baseline comparisons are critical, as what appears to be a pattern of improved performance in explainable prescriptive analytics may be put in jeopardy by introducing seasonal trends, policy changes, and/or prior trends.
Causal auditing can help make the outcomes of prescriptive analytics more credible in Canada, as it tests whether the recommended action leads to the outcomes in addition to just being correlated with them. These are: assumptions, credible counterfactuals, subgroup analysis, uncertainty, and operational economics all in one. That's the standard that transforms analytics from persuading a prediction to evidence for responsible intervention.
CITE THIS ARTICLE
CHOWDHURY, S. A. (2026). Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms. https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3
S. A. CHOWDHURY, “Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms,” 2026. [Online]. Available: https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3
CHOWDHURY, S. A. (2026) ‘Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms’. Available at: https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3
CHOWDHURY, SABBIR AHMED. “Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms.” 2026, https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3.
SABBIR AHMED CHOWDHURY. “Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms.” (2026). https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3.
CHOWDHURY SA. Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms. 2026. https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3
@misc{article_b9eefdc811b258f3bc0466d28e324fc3,
  title = {Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms},
  author = {SABBIR AHMED CHOWDHURY},
  year = {2026},
  url = {https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3},
}
TY  - GEN
AU  - SABBIR AHMED CHOWDHURY
TI  - Auditing Explainable Prescriptive Analytics with Causal Evidence Across Canadian Firms
PY  - 2026-06-30
UR  - https://www.sabbirresearchhub.com/article/b9eefdc8-11b2-58f3-bc04-66d28e324fc3
ER  -
AI-enabled employee engagement includes survey analytics, sentiment analysis, personalized recommendations, workforce listening, communication tools, and manager decision support, all operating within sensitive employment relationships. The article compares humans and algorithms on matched tasks, information, and outcome horizons rather than benchmark scores alone. Human context and judgment are weighed against algorithmic scale and repeatability, while hybrid rules, disagreement analysis, blind
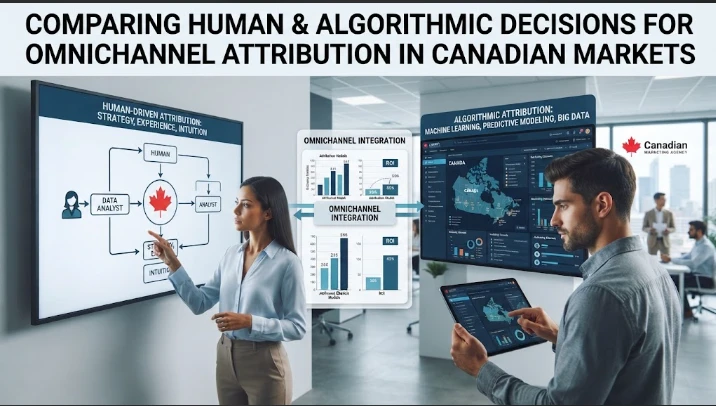
This article compares human and algorithmic decision making for Omnichannel Attribution in Canadian Markets, focusing on downstream decision quality rather than prediction accuracy alone. It estimates how online and offline touchpoints contribute to conversion, while identity gaps, walled-garden platforms and the difference between observed credit and causal incrementality complicate interpretation. Human judgment contributes context, tacit knowledge, strategic interpretation and sensitivity to
AI business model renewal concerns changes in value creation, value delivery, and value capture through AI-enabled services, workflow redesign, personalization, pricing support, and new information products. The article emphasizes real-world causal testing through random assignment, phased rollouts, encouragement designs, or cluster experiments. It calls for pre-specified outcomes, contamination controls, comparisons among human-only, algorithm-only, and hybrid workflows, and stop rules when har