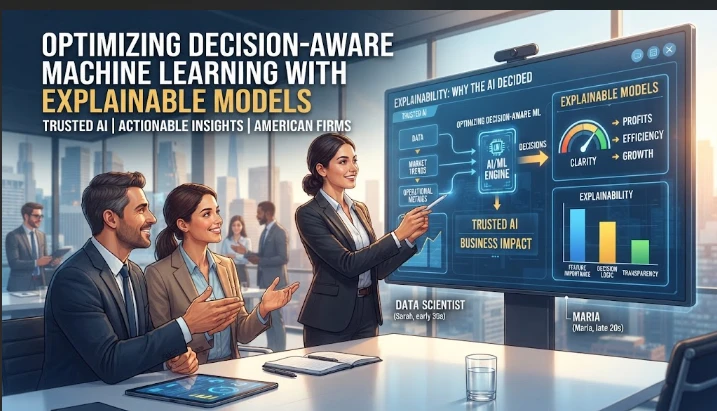
In U.S. Decision-Aware Machine Learning is no longer a specialist analytics discussion, but rather a management question by 04 August 2026. The question was not whether scores, forecasts, rankings, or recommendations could be generated with advanced models, it was what could be generated. More focus shifted to the question of whether those outputs could continue to be reliable, understandable, fair, and economically useful when linked to real decisions. For organizations that invest in decision-aware machine learning, the shift shifted what was previously considered “successful implementation” – just good technical performance – to “evidence-based decision quality.”
Decision-aware machine learning cannot be separated from action; it is more a process of prediction to guide it. But that distinction is important because the same degree of accuracy can yield significantly different business outcomes with different thresholds, resources, and costs of error. American companies are thus better able to learn from the linkage between model output and actual decisions, actual results, override behavior and modifying operating conditions, than from the award of a single "benchmark score.
Explainability gains value when it alters the decision and not just is positioned in a dashboard. Local explanations can indicate what is going on to produce a specific score and global explanations can point to the dominant patterns throughout a portfolio. All views should be linked to action rules. Without an explanation that a decision owner can interpret there's not much operational value.
Optimization of the model is not just about maximizing predictive performance. Different trade-offs are provided by transparent generalized models, monotonic constraints, interpretable ensembles, post-hoc explanation methods and calibrated probability estimates. Selection should reflect such things as the cost of mistakes, the need to contestability, the level of stability of the explanations, and the complexity of the operating environment. However, a lower benchmark score may lead to better business performance if decision makers are aware of and trust the behaviour of the models.
Stability is also a factor in the quality of the explanation. Even when the predictions appear consistent, the confidence in the story decreases if it experiences dramatic shifts in the story's explanation given slight variations in the input. Fragile explanations can be found through sensitivity checks, counterfactual tests, feature perturbations, or comparisons between subgroups and repeated estimation. Stable explanations are particularly vital in decisions that impact on employment, access, pricing, safety and other consequential outcomes.
However, feature importance is not necessarily a causal relationship. A variable can be very predictive as it can represent a proxy, it can be an outcome of previous decision or it can be correlated to a driver not observed. Explainable modeling requires domain knowledge in addition to the statistical interpretation. Before deciding to intervene, business teams must differentiate between prediction, association and causal evidence.
There are also constraints, which can be specified explicitly, that can be included in optimization. Fairness thresholds, monotonic relationships, the maximum error rate, calibration targets, operational capacity, and review requirements can all be part of model selection. These restrictions translate organizational values into measurable design conditions. This opens up the system to more effective defense as optimization is not based on a single abstract variable but rather on the actual decision context.
American AI governance had a multi-layered, not one-size-fits-all approach, ranging from civil rights laws at the federal level, consumer protection, sector regulations, state initiatives, and local needs. In 2023, NIST published their AI Risk Management Framework, which breaks risk work into four phases – Govern, Map, Measure, and Manage – and explicitly identifies data drift, model drift, and concept drift as indicators for maintenance. Employment tech was given extra attention given the EEO Commission's previous statement that current anti-discrimination laws apply if software, algorithms, or AI are part of making an employment decision.
Explicit uncertainty communication is also critical for the development of strong analytical practice. Consider the possibility that point estimates can be misleading in situations where there is sparse data or conditions are rapidly evolving. Uncertainty becomes apparent to operational teams through prediction intervals, sensitivity ranges and scenario analysis, and confidence categories. Eliminating language of uncertainty paves the way for proportional responses, not automatic acceptance of all scores.
Vendor governance is also important as external platforms may change models, interfaces, data processing or terms, without being released at a comparable internal pace. Documentation, change notification, audit access, incident handling, security, data retention, exit arrangements should all be covered in contracts. Independent validation is still required for internal teams for vendor assurance to be replaced with evidence.
Business value should be assessed throughout the business lifecycle. Development is just the start, there's integration, training, monitoring, data upkeep, review time, remediation and retirement to cost too. Costs should be matched up with benefits. A model that requires considerable manual adjustment may appear good in a pilot, but may deliver poor overall results after scaling.
When the results from monitoring are fed into process design, organizational learning is the key source of return. When there are repeated misalignments between data and frontline judgment, it can reveal variables that are missing or out-of-date rules. When a model fails, it may be due to the labels or business definitions that are used repeatedly. Considering those signals as learning opportunities is a better decision system than just retraining on schedule.
Business unit, customer group, geography, channel, or operating regime should also be segmented if they have an impact on the machine learning that drives business decisions. Data dictionaries and common metric definitions eliminate conflicts that only manifest themselves as performance issues.
It is important to perform a baseline comparison as apparent progress in the decision-aware machine learning may be lost once seasonal trends, policy changes, or previous trends are considered. Independent review is most effective when reviewers can replicate important outcomes from input data, assumptions, and versions of model artefacts and/or code.
Operational teams get a limited number of decision relevant indicators instead of a large dashboard with no logic on how to escalate. In the development phase, scenario testing can reveal brittle behavior through pushing or pulling rare cases, missing inputs, sudden fluctuations in volume or unusual cases before deployment.
Data dictionaries and common metrics definitions resolve comparison disagreement before it even becomes an issue when performance is not up to scratch. Monitoring should also cover both the mean and tail results since some extreme faults may be more important than modest improvements in a mean statistic.
Independent review is most helpful when the reviewers can replicate critical results from raw data sources, assumptions documented, and version controlled model artifacts, or code. Feedback from frontline users is also critical in change management as workflow friction can kill the value even if analytical performance is unchanged.
When deploying, scenario testing can identify brittle behavior in a system, as it can be asked to test rare combinations, missing inputs, abrupt volume changes and/or unknown scenarios. Clear rules for retirement are important because models that are no longer effective and efficient can stay alive in the organization for too long because of a lack of organizational inertia.
The monitoring should also cover tail results as well since errors that are extreme can be more important than minor changes in a mean figure. Decision logs make for great evidence after the fact of linking decisions, over-riding decisions, context and outcomes.
There should also be feedback from frontline users, as workflow friction can diminish the value achieved even if the analytical performance is as good or better. Cost-sensitive evaluation adds realism by structuring the consequences of a false positive as being different than a false negative, delayed action, or unnecessary escalation.
A clear retirement rule is important because the past can remain in place within an organization for a long time after there is evidence to support its replacement. If it is suspected that a simpler rule, an updated baseline or another model is working better than the existing model, periodic challenge exercises can be used to determine if that is the case.
Decision logs is a useful artifact for subsequent post mortem, connecting reccomendations, overrides, context and actual results. In addition, evidence must be broken down into business unit, customer group, geography, channel or operating regime where those segments influence decisions that inform machine learning.
Cost-sensitive evaluation enhances realism by varying the outcomes of false positives, false negatives, delayed action, and unnecessary escalation. Comparisons are important because of the potential for apparent improvement in decision-aware machine learning to vanish once seasonal patterns, policy changes, or previous trends are considered.
Explainable optimization provides a practical pathway for a more robust adoption and control of decision-aware machine learning in the United States. The point is not to be as transparent as possible, but to be transparent as much as it can help to challenge, correct, and to do better. The usefulness of models is enhanced by considering the trade-offs between their performance, interpretability, fairness, stability, and operational constraints.